

The advent of all-flash Solid-State Drives (SSDs) has transformed the storage function in enterprise and cloud computing. SSDs offer much better storage performance than traditional spinning hard disk drives (HDDs). It is therefore not surprising that 18% of businesses now use all-flash storage, with industry research predicting that another 14% will have adopted it by 2022. The all-flash storage market is growing briskly at 11% per year. The adoption of compute acceleration technologies, more modern applications, and faster storage media is pushing IT infrastructure architects to confront a networking challenge: getting data from storage media to the application that needs it.
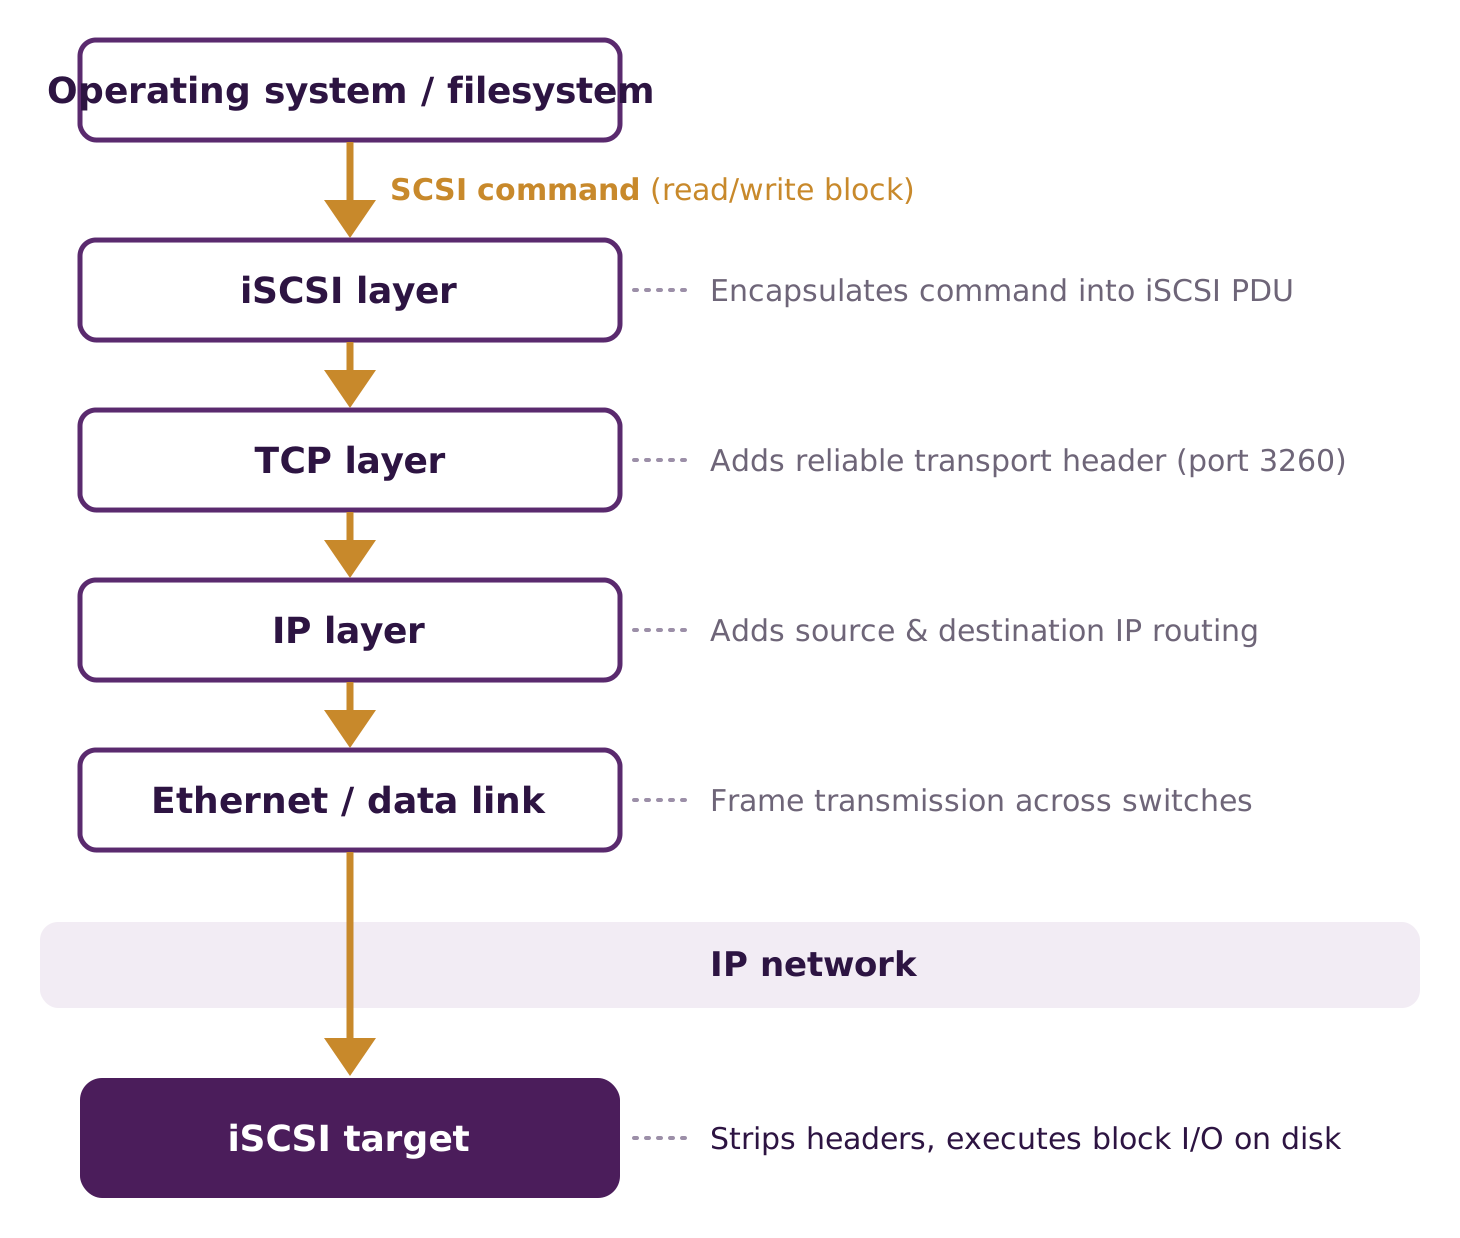
Most infrastructure now in place relies on the Internet Small Computer Systems Interface (iSCSI) standard–the networked version of the bus SCSI protocol–to link storage with servers. iSCSI carries SCSI commands over a TCP/IP network in order to deliver block-level access to storage devices. The difficulty is that iSCSI is a serial technology. It is therefore far too slow to accommodate the massively parallel nature of solid-state storage drives. Non-Volatile Memory (NVM) Express, or NVMe, is a much better solution for this workload.
However, NVMe, too, has drawbacks. For example, NVMe devices deliver strong performance but can suffer from local “puddling” of storage resources. The innovative NVMe over Fabrics (NVMe-oF) protocol will work well in theory, but in reality, the various implementations- Fibre Channel (FC), RDMA over Converged Ethernet (RoCE), InfiniBand, iWARP, TCP/IP are not all created equal in terms of ease of use and cost. Thus, selecting the right option can be difficult. In contrast, NVMe over TCP/IP is superior in all respects: performance, ease of use, and cost-efficiency, because it uses standard TCP/IP networking.
What is iSCSI?
SCSI – literally Small Computer Systems Interface. This protocol has been the de facto standard for computer and server access to storage for decades. The SCSI set of standards is used to carry blocks of data over short distances using a variety of serial and parallel busses internal to a computer. The widespread use of the Transmission Control Protocol/Internet Protocol (TCP/IP), which connects computer systems to networks such as the Internet, brought SCSI and the Internet together, creating iSCSI.
To understand iSCSI, you first need to understand the basic SCSI protocol. SCSI is a block-based set of commands designed for Direct-Attached Storage (DAS) use cases. Through SCSI commands, a computer can instruct storage media to spin up and read and write data. In SCSI, the client is called the “initiator.” The storage volume it accesses is called the “target.”
SCSI communication between an initiator and target uses a command queue. The initiator sends commands to be performed by the target in a queue. The initiator then receives data and acknowledgments for each of its queued commands. There is a single queue for each connection between an initiator and target.
How iSCSI Works
The IT hardware industry has addressed the need to connect storage devices to computers for decades. Starting in the 1990s, companies like Apple and Microsoft worked together to publish the original SCSI X3.131-1986 standard, known as “SCSI-1” with the X3T9 technical committee of the American National Standards Institute (ANSI). In this effort, the industry adopted the American slang term “scuzzy,” which connotes sloppy, unattractive behavior, as an ironic counterpoint to the technology’s slick capabilities.
Based on a shared-bus transport model, SCSI comprises standards for physically connecting and transferring data between peripheral devices and computers. It defines protocols, commands, and interfaces for almost any kind of peripheral, but in practice, it was mostly used for hard disk drives.
Computers and storage technologies grew larger and faster over time. With the resulting increases in bandwidth and distance requirements, the industry developed several new serial SCSI transports, including:
- Fibre Channel (FC)—a high-speed data transfer protocol that provides lossless delivery of raw block data. FC is mostly used to connect storage to servers in storage area networks (SANs). An FC network is a “switched fabric,” named so because its switches operate in unison, effectively as “one big switch.” FC networks usually run on fiber optic cables.
- Serial Attached SCSI (SAS)—a point-to-point serial protocol that moves data in and out of storage devices like HDDs or tape drives. It uses the standard SCSI command set.
- SCSI over TCP/IP (iSCSI)—a transport layer protocol that works over the Transport Control Protocol (TCP). iSCSI makes it possible to transport block-level SCSI data between an iSCSI “initiator” and a storage device using common TCP/IP network connections.
SCSI vs. iSCSI
iSCSI is SCSI transport over TCP/IP and designed for Network Attached Storage (NAS) use cases. With iSCSI, therefore, a connection between the initiator and target consists of a single TCP/IP socket opened by a single thread. Because iSCSI updates the ubiquitous SCSI storage protocol, computer operating systems (OSs) implemented the same model in their storage stacks. iSCSI means access to a storage volume is always mediated by a single queue, corresponding to the single queue in the connection between the initiator and target.
Benefits of iSCSI
iSCSI has become the standard for block storage over standard networks because TCP/IP is widely adopted there. However, this is not optimal from a performance perspective. The issue is that applications that need low latency now use SSDs, and iSCSI is not designed to work well with them. Instead, TCP/IP protocols simply transport the same original SCSI protocol developed for spinning hard drives.
This single-queue model wasn’t a problem for many years. HDDs suited the single queue because most had a single read/write head. Flash memory behaves quite differently. It does not use a “single head” to serialize data access. Instead, flash memory is arranged in banks of storage elements, similar to dynamic random access memory (DRAM).
Servers have also changed, further affecting the efficacy of the single-queue iSCSI model. A typical server today may have dozens of CPU cores. As a result, storing data from several cores in parallel requires locks on the single storage queue. This isn’t a big problem for spinning HDDs, which deliver only about 100 IOPs. A typical enterprise storage system built with HDDs might perform at several thousand IOPs per volume. When storage migrates to flash, this all changes dramatically.
The single queue model is problematic with flash SSDs. A single SSD can deliver hundreds of thousands of IOPs. The resulting queue contention becomes a serious performance issue for a server with many cores. The iSCSI single-queue model creates further difficulties when using the standard single-thread, single-TCP-socket implementation.
It is possible to perform multipath I/O by surfacing a logical unit via several target ports and load balancing I/O over multiple threads and sockets. But this strategy is complicated to manage on the target side. It invariably suffers from queueing issues on the initiator side. The operating system still treats multiple paths as a single device. Performance will inevitably lag.
Limitations of iSCSI
iSCSI enables cost-effective block-level storage over standard Ethernet, but it introduces notable performance and operational trade-offs compared to dedicated Fibre Channel fabrics. Encapsulating SCSI commands within TCP/IP frames incurs significant CPU overhead on host systems and storage targets unless costly TCP Offload Engine (TOE) hardware is deployed. Because iSCSI often shares bandwidth with general network traffic, congestion and packet drops can cause latency spikes and connection instability. Furthermore, achieving reliable performance requires complex network engineering—such as implementing dedicated VLANs, Jumbo Frames, and Quality of Service—while baseline data streams remain vulnerable to interception unless augmented with CHAP authentication or IPsec encryption.
- High CPU Overhead: TCP/IP frame encapsulation and processing consume host CPU cycles unless offloaded to specialized network interface cards (TOE or iSCSI HBAs).
- Latency and Contention: Sharing Ethernet infrastructure with general LAN traffic creates packet loss, jitter, and latency spikes under heavy network loads.
- Complex Network Tuning: Optimal throughput requires non-trivial manual configuration, including isolated subnets/VLANs, Jumbo Frames (MTU 9000), and strict QoS.
- Security Exposure: Transmitting storage commands over standard IP exposes traffic to eavesdropping and spoofing, necessitating extra security layers such as CHAP authentication or IPsec overhead.
- Distance Sensitivity: Although routable across wide-area networks (WANs), TCP acknowledgment delays and packet retransmissions rapidly degrade block-level storage performance over long distances.
Evolution of Storage Protocols
To get better performance from SSDs, a new communication protocol was needed. Over ninety companies collaborated through the NVM Express Workgroup. Intel was one of the leading firms in the effort to develop the resulting open, logical-device interface specification that lets a computer access non-volatile (i.e., flash) storage media. Typical implementations used a machine’s PCI Express (PCIe) bus.
NVM Express®, or NVMe®, is designed to leverage SSDs’ internal parallelism and inherent low latency. NVMe lets host hardware and software exploit parallelism extensively. As a result, NVMe reduces I/O overhead and improves performance compared to iSCSI.
NVMe has been transformative, emerging as the new standard protocol for accessing high-performing SSDs. However, NVMe was initially designed for direct-attached PCIe SSDs. The specification could not work for networked storage. To address this limitation, the NVMe working group developed NVMe-oF®, which supports a rack-scale remote pool of SSDs over network fabrics.
The IT industry has generally accepted that NVMe-oF will replace iSCSI as the preferred communication method between compute servers and storage servers. It will become the default protocol for disaggregating storage and compute servers.
However, NVMe-oF has limitations. Initial deployment options for NVMe-oF were limited to Ethernet over Remote Direct Memory Access (RDMA) and Fibre Channel fabrics. These options suit only small-scale deployments. Indeed, most data centers do not currently support NVMe over Fabrics using technologies such as RDMA or Fibre Channel.
Issues with RDMA or Fibre Channel include:
- Requiring specialized, not commonly used equipment for data centers
- Being generally out of the mainstream
- Requiring significant changes in the data center’s network infrastructure
- Locking the customer to a single vendor
Why NVMe/TCP Emerged
Given NVMe-oF’s potential, but also its limitations, it made sense for the industry to find a way to leverage NVMe’s performance characteristics while using the predominant TCP/IP network transport protocol. This led to NVMe/TCP. Lightbits Labs, working in collaboration with Facebook, Intel, and other industry leaders, is extending the NVMe-oF standard to support TCP/IP.
This approach complements RDMA fabrics, with NVMe/TCP disaggregation offering simplicity and high efficiency. TCP is ubiquitous, scalable, and reliable—ideal for short-lived connections and container-based applications. Additionally, migrating to shared flash storage with NVMe/TCP requires no changes to the data center network infrastructure. This lack of infrastructure changes should make deployment across the data center relatively easy. After all, nearly all data center networks are designed to carry TCP/IP.
Furthermore, broad industry collaboration on the NVMe/TCP protocol makes it likely that NVMe/TCP will become a broad ecosystem supporting a wide range of operating systems and NICs. For instance, the NVMe/TCP Linux drivers are a natural match for the Linux kernel. They use the standard Linux networking stack and NICs without any modifications. As a result, NVMe is showing great promise as a new protocol. It is suitable for hyperscale data centers, among other use cases, because it is easy to deploy without changing the underlying network infrastructure.
The NVMe specification supports highly parallel access to solid-state storage. There is no single bottleneck. Thus, I/O to an NVMe “namespace,” the equivalent of the SCSI logical unit, can be performed via 64,000 queues with up to 64,000 commands per queue. This parallel access is a critical architectural development because multiple queues eliminate the contention inherent in the SCSI model.
iSCSI vs. NVMe/TCP
Comparing NVMe/TCP to iSCSI, the following benefits emerge:
- Extends NVMe across the entire data center using a simple and efficient TCP/IP fabric
- Enables disaggregation across a data center’s availability zones and regions
- Leverages TCP/IP transport to bring low average and tail latencies to a highly parallel NVMe software stack
- Requires no changes to the networking infrastructure or application servers
- Delivers a high-performance NVMe-oF solution that has the same performance and latency as Direct Attached SSDs (DAS)
- Uses an efficient and streamlined block storage software stack optimized for NVMe and existing data centers
- Provides parallel access to storage optimized for today’s multi-core application/client servers
- Supports a standards-based solution that will have industry-wide support
What is the Difference Between NVMe/TCP and iSCSI
How does the NVMe/TCP stack compare to iSCSI in terms of performance? Lightbits conducted a side-by-side comparison of the two technologies to arrive at benchmark results. The test used the industry-standard Flexible I/O Tester (FIO) benchmark tool with identical setups for iSCSI and NVMe/TCP. Specifically, the test used an initiator with a dual-socket Intel® Xeon® E5-2648L v4 processor running at 1.8 GHz, with 14 cores per socket and two hyperthreads per core. The target machine had the same socket and core count. It ran Xeon E5-2650L v4 processors at 1.7 GHz. Each target used Intel DC P3520 SSDs (450 GB).
The test performed all I/O via Mellanox ConnectX-4 100GbE NICs on both machines. Both initiator and target machines ran Linux 4.13.0-rc1 kernel release. For iSCSI, we used the kernel’s stock iSCSI initiator. For NVMe/TCP, the test used an open-source initiator contributed by Lightbits. For iSCSI storage, we configured a 12-drive RAID-0 group; for Lightbits NVMe/TCP, the exported namespace used the same hardware and the same 12 SSDs.
The benchmark demonstrated a typical multithreaded I/O-bound application. Such applications often open a thread per task, with each thread performing a single I/O (i.e., multiple threads, each with an I/O queue depth of 1) at a time. Then, we varied the number of threads to measure I/O scalability as the thread count increased. Varying the number of threads was a critical test for applications running on modern servers with dozens of CPU cores. The I/O mix was 70% reads and 30% writes.
Before running the benchmarks, we fully overwrote all SSDs to precondition the tests. For iSCSI, we set the maximum commands per session to 2048 and the logical unit queue depth to 1024. Both parameters were the implementation maximums. With these settings, the test reflected a reasonable comparison of the two TCP-based protocols with identical hardware and software configurations.
The results: iSCSI peaked at 89K IOPS with 128 threads over two multipathed target connections in active-active mode. This IOPS amount was the maximum I/O performance the application could achieve. Multipathing over two target connections provided minimal benefit compared to a single connection.
It is also troubling that above 64 threads, iSCSI averaged latencies over a millisecond. This I/O performance is unacceptable for flash drives in today’s massively multi-core hyperscale cloud services. These findings illustrate iSCSI’s inherent performance problem. The protocol’s single-queue, single-threaded model limits scalability.
The NVMe/TCP test result showed the benefits of the natively multithreaded architecture. I/Os for a single volume (NVMe namespace) easily rose to 725K IOPS in this application scenario. This is an order of magnitude higher IOPS for the application. Moreover, at 256 threads, the initiator did not saturate. Importantly, NVMe/TCP I/O latencies were much lower than iSCSI latencies at a similar thread count and much lower IOPS. Even at 256 threads and 725K IOPS, NVMe/TCP latency was still under 500μs.
Why NVMe/TCP is the Right Choice for Cloud Application Acceleration
SSD growth is creating a performance conflict. The iSCSI single-threaded model isn’t optimal for connecting compute servers to network-attached SSDs. Instead, NVMe delivers far superior performance characteristics. That said, some NVMe-oF solutions have distinct limitations because they require specialized components. NVMe/TCP offers a solution. It enables NVMe over the standard, common TCP/IP network transport protocol. In side-by-side tests, NVMe/TCP vs. iSCSI NVMe is clearly resolved. NVMe/TCP enables IOP performance an order of magnitude higher than iSCSI.
Frequently Asked Questions: iSCSI
What is iSCSI and how does it work?
iSCSI (Internet Small Computer Systems Interface) is a transport layer protocol that facilitates block-level data transfers over standard IP networks (typically Ethernet).
Instead of connecting hard drives or SSDs directly via physical cables (SATA, SAS) or deploying a specialized, expensive Fibre Channel (FC) storage area network (SAN), iSCSI allows a host computer to treat remote storage across a local network or the internet as if it were a locally attached, raw physical disk.
Is iSCSI still used in modern data centers?
Yes. It remains used in data centers, primarily in VMware/virtualized clusters and backup tiers, for block storage over 10/25/100GbE, though NVMe-oF handles ultra-low-latency flash workloads.
What are the limitations of iSCSI storage?
This is answered in more detail above. In summary, key limitations include high host CPU overhead from TCP/IP encapsulation, latency spikes from network congestion, and complex configuration needs (isolated VLANs, Jumbo Frames). It also lacks built-in encryption, requiring CHAP or IPsec, and cannot match the ultra-low latency of newer protocols like NVMe-oF.
Why is iSCSI slower than NVMe/TCP?
SCSI is a 40-year-old protocol designed to support diverse physical devices (tape drives, optical discs, scanners, printers, and hard drives). Both iSCSI and NVMe/TCP run over standard Ethernet and use TCP/IP for transport, but NVMe/TCP is significantly faster because it eliminates the legacy architectural bottlenecks of the SCSI command set.
| Metric / Feature | iSCSI | NVMe/TCP |
|---|---|---|
| Max Queues | 1 (historically shared) | Up to 64,000 queues |
| Queue Depth | Up to 256 commands | Up to 64,000 commands per queue |
| Core Mapping | Threads contend for locks | 1:1 queue-to-CPU core mapping (lockless) |
| Protocol Overhead | Heavy, variable-length SCSI CDBs | Lightweight, fixed 64-byte command set |
| Internal SSD Translation | Required (SCSI $\to$ NVMe) | None (End-to-end native NVMe) |
| Relative Latency | Baseline (~100–250 µs overhead) | 30%–70% lower latency than iSCSI |
| Throughput & IOPS | Drops under multi-core load | Scales linearly with CPU core count |
Can iSCSI handle SSD performance efficiently?
No. While iSCSI easily saturates SATA and SAS SSDs, its legacy SCSI stack relies on shallow queues and single-lock serialization. This creates severe CPU bottlenecks and latency overhead, leaving millions of IOPS and the microsecond-level potential of today’s NVMe drives bottlenecked and unexploited.
What replaces iSCSI in modern storage systems?
NVMe/TCP is the primary replacement for iSCSI in modern storage systems, delivering block-level storage over existing Ethernet switches without specialized hardware. By eliminating the legacy SCSI command stack, NVMe/TCP enables massive parallel queuing, much lower CPU overhead, and microsecond-level latency, letting organizations fully saturate modern all-flash arrays over existing network infrastructure.
Is iSCSI suitable for cloud-native workloads?
While container platforms like Kubernetes support iSCSI via CSI drivers and legacy volume plugins, iSCSI’s underlying architecture was built for static, monolithic environments rather than the dynamic, ephemeral, distributed nature of cloud-native systems. Where the Friction Lies:
- Slow Attachment and Pod Rescheduling: Cloud-native workloads expect pods to spin up, terminate, and migrate across nodes in seconds. iSCSI attachment requires target discovery, TCP session handshakes, OS-level LUN mapping, and device formatting. When a node fails, releasing locked iSCSI sessions and reattaching the LUN to a new node frequently causes failover delays or mount-timeout errors.
- Host Coupling and Node Bloat: Containers are meant to be decoupled from host operating systems. However, consuming an iSCSI volume typically requires host-level tools (open-iscsi, iscsid, multipath daemons) and specific kernel modules loaded on every Kubernetes worker node. This conflicts with lightweight, immutable container operating systems.
- Strict ReadWriteOnce (RWO) Constraints: iSCSI exposes raw block devices formatted with standard filesystems. Only a single container node can safely mount that volume at a time (RWO). It cannot natively provide shared multi-pod access (RWX) without running a distributed clustering filesystem on top.
- Scale Limitations with LUNs: Highly scaled microservices may launch thousands of isolated stateful pods. Managing thousands of individual iSCSI targets/LUNs creates configuration bloat, strains storage controllers, and hits connection limits that traditional SAN appliances struggle to support dynamically. Concurrency and CPU Overhead: High-density container nodes run hundreds of concurrent application threads. iSCSI’s shallow command queuing and host CPU TCP encapsulation can quickly bottleneck I/O-heavy containerized databases.
What are the disadvantages of iSCSI protocol?
The comprehensive answer is above. In summary, key disadvantages include high host CPU overhead from TCP/IP encapsulation, latency spikes from network contention, and complex setup requirements (VLANs, Jumbo Frames, MPIO). It also lacks native data encryption, relies on shallow queues that bottleneck modern NVMe SSDs, and suffers performance drops over WAN latency.
When should iSCSI be used today?
Use iSCSI when you need shared, raw block-level storage and the application doesn’t require microsecond-level latency. It occupies the practical middle ground between expensive, specialized Fibre Channel SANs and ultra-high-performance NVMe fabrics.
| Avoid iSCSI If You Need… | Preferred Protocol | Why |
|---|---|---|
| All-Flash NVMe array performance | NVMe/TCP | Modern NVMe SSDs provide microsecond latency and millions of IOPS; iSCSI’s single-queue SCSI architecture bottlenecks them. |
| Microservices & Kubernetes pods | CSI with Container-Attached Storage (e.g., Lightbits SDS) | Dynamic container rescheduling and ephemeral pod movement cause frequent LUN timeout/locking headaches with iSCSI. |
| Zero-loss mission-critical enterprise SANs | Fibre Channel | Zero-packet-loss guarantees and hardware-enforced flow control without tuning Ethernet congestion. |
| Shared multi-node file access (RWX) | NFS | iSCSI exposes raw, unmanaged block volumes; mounting an iSCSI volume on multiple non-clustered nodes can cause immediate data corruption. |
